Infrastructure detection
Source: src/app/infrastructure/detection
Detecting objects in a video is three separate jobs, and Blurzy keeps them in three packages so that each can change without the others noticing:
| Package | Job | Page |
|---|---|---|
model |
Load one provider's network and translate its output into DetectionResult values |
Models and providers |
engine |
Hold the selected model and answer "what is in this one image?" | Engine |
worker |
Loop over video frames on a background thread, batch results, report progress | Worker |
Where this sits
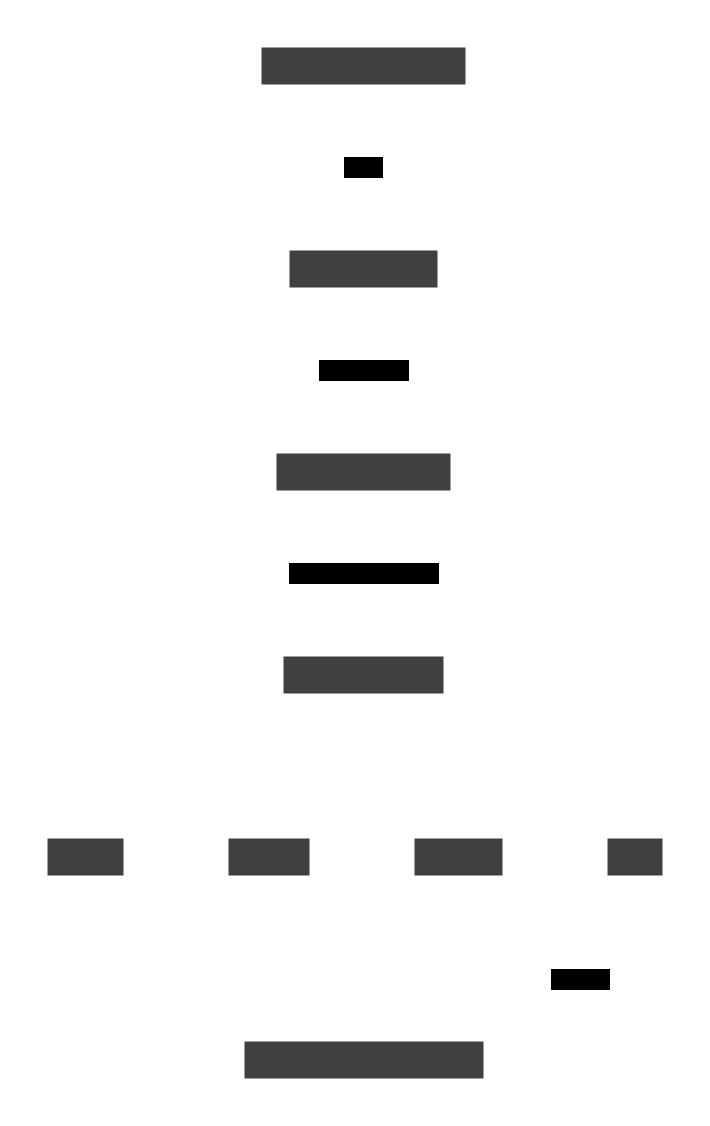
Arrows read top to bottom as ownership and call direction. The four provider boxes are alternatives: one is chosen when the engine is built, not run in sequence. Whatever is chosen, callers receive the same result shape.
Ownership boundaries
- The engine does not iterate video; the worker does.
- Neither decides annotation layers. The Application Detection service stores batches as Layer A (original detector output) and seeds Layer B (reviewed, editable detections). See Video layers.
- Selecting a model is a UI/Application workflow; the model package only knows how to turn a name into a wrapper.
Reading order
- Models and providers: how a name such as
YOLOv8nbecomes a wrapper, what each provider family does, and how mappers normalise output. - Engine: the one-image boundary and its failure behaviour.
- Worker: the frame loop, caching and batch signals.